
Table of Contents
Last week was about Terraform module boundaries: what belongs inside a module, what belongs in a helper, and what the golden path is responsible for assembling. But boundaries on their own don’t do anything. They only matter once something calls the module, and that’s where a lot of platforms quietly fall apart.
Calling conventions are the rules for how one module talks to another: where the Terraform module source points, which version gets used, what goes in and what comes out.
Where the Terraform module source points
Every module call starts with a source. With the module-repo approach from the repo structure post, that’s usually a Git source:
module "web_app" {
  source = "git::https://github.com/<org>/tf-azurerm-web-app.git?ref=v1.8.2"
}
The bit that matters is the ?ref=. With a Git source, that’s your pin. The version argument you’ll see in a lot of examples only works for registry sources, so if you’re pulling from Git and set version, Terraform won’t quietly use it. It will reject the configuration.
The convention I’d hold to is simple: no module call ever points at a branch. Not main, not develop, not “just for now.” A branch ref means the code you plan against today isn’t necessarily the code you apply against tomorrow, and nobody downstream will know it’s changed until something breaks.
Pinning: tags, SHAs and who pins what
A tag is the normal choice, and the mechanics of cutting them are covered in the provider pinning post, so I won’t repeat that here.
The caveat is that Git tags aren’t immutable. Someone with the right permissions can delete a tag and push it again pointing at different code. If that worries you, either protect your tags with a repository ruleset or pin to a full commit SHA instead. The SHA is the only ref that genuinely can’t move, at the cost of being unreadable to humans. For most platform teams, protected semver tags are the sensible middle ground.
The more interesting question is who pins what.
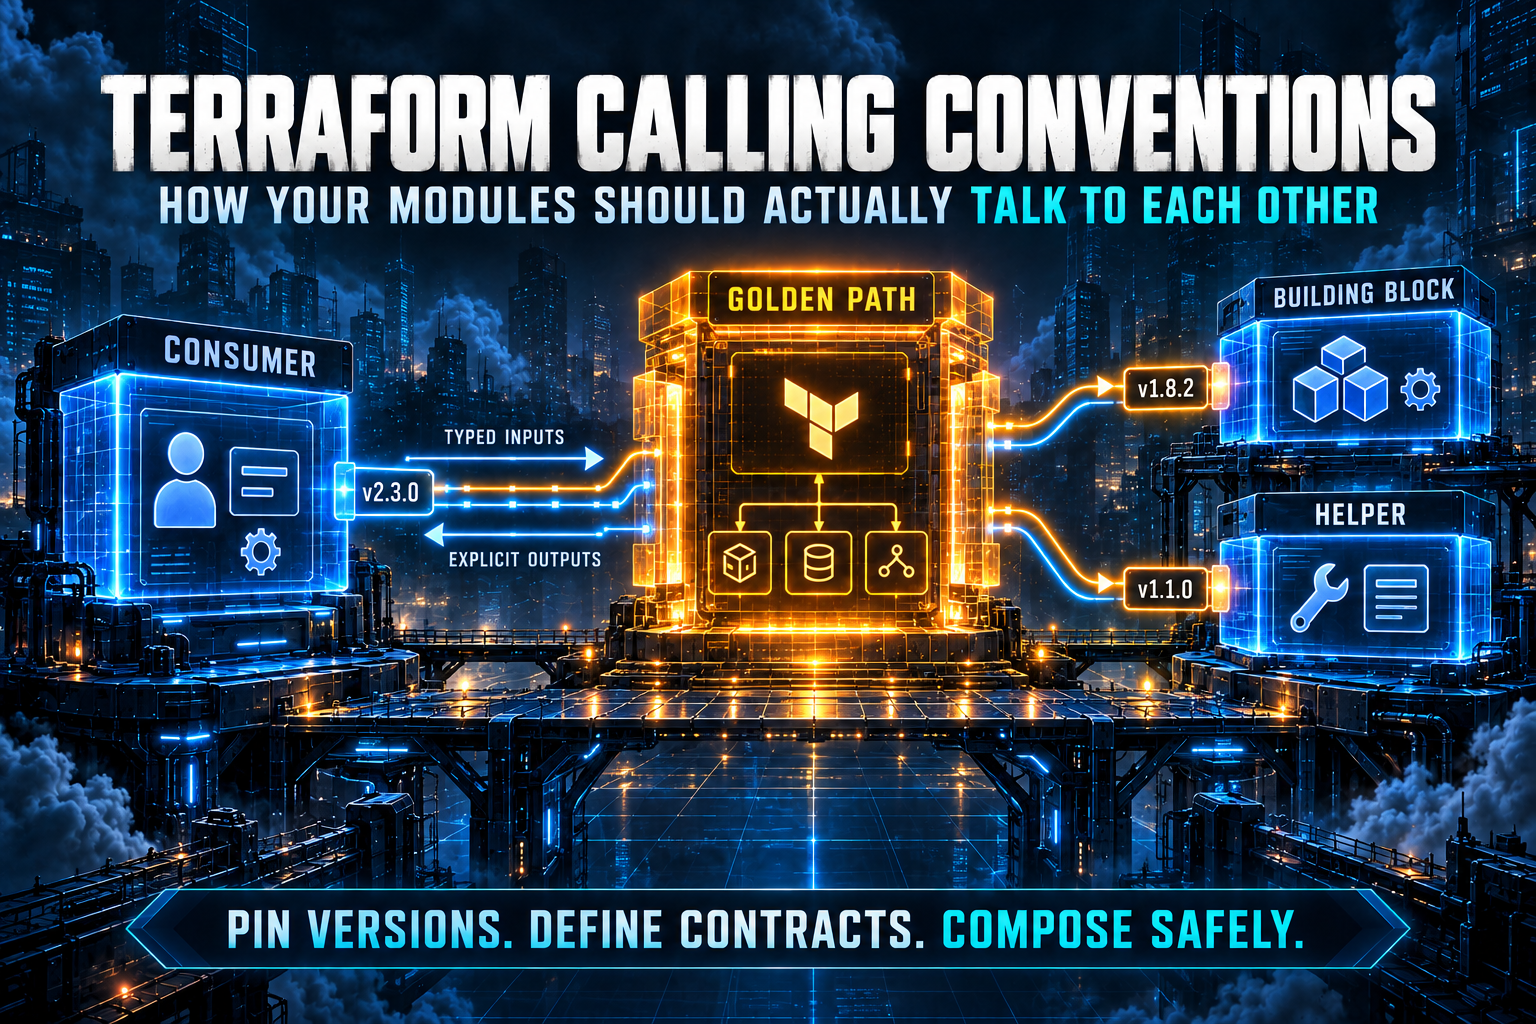
If the golden path is published as a versioned module, the convention should be:
- The consumer pins the golden path.
- The golden path pins its building blocks and helpers.
- The consumer never pins a helper directly.
That last one is important. The moment a consumer repo calls the private endpoint helper directly, alongside a golden path that also calls it, you’ve got two versions of the same logic in one deployment and no clear owner of which one is right.
Keeping the pins layered means upgrades flow in one direction. A helper gets a fix, the golden path takes it and cuts a new release, and consumers pick that up by bumping one ref. It’s the same “someone has to decide to take the update” principle from the repo structure post, just applied one layer down.
Inputs are a contract
A module’s variables are its API. Treat them that way.
That means typed inputs rather than any, grouped into objects where things genuinely belong together, with sensible defaults via optional():
variable "database" {
  type = object({
    enabled = optional(bool, false)
    sku     = optional(string, "S0")
  })
  default = {}
}
It also means validation for anything the platform has an opinion on:
variable "environment" {
  type = string

  validation {
    condition     = contains(["dev", "test", "prod"], var.environment)
    error_message = "environment must be one of dev, test or prod."
  }
}
A failed validation at plan time is a much cheaper conversation than a misnamed production resource.
One convention that saves a surprising amount of pain: building blocks take IDs, but humans shouldn’t be the ones typing them. If a module needs a subnet, it should take a subnet_id, not a subnet name, VNet name and resource group name so it can look the subnet up itself. But that ID should come from Terraform, not from someone copying it out of the portal into a tfvars file.
I’ve been bitten by this with Log Analytics. Azure treats resource IDs as case-insensitive, Terraform doesn’t, and a hardcoded workspace ID with slightly different casing to what the provider returns is enough to produce a diff that shouldn’t be there. Resolve it with a data source instead and the provider gives you the ID in the form it expects.
So the lookup happens once, at the top, in the golden path or the consumer’s root, and the resolved ID gets passed down. Every module doing its own lookup is another place a typo can break a plan. Every human pasting IDs is another place casing can.
Outputs are a contract too
Outputs get far less thought than inputs, which is odd, because they’re what makes composition possible at all. module.web_app.id only works because someone decided to output it.
A few conventions worth holding to:
- Output the things callers will genuinely need, named explicitly:
id,name,principal_id, not the entire resource object. - Outputting a whole resource “in case someone needs something” couples every consumer to that resource’s internal shape, and can leak sensitive attributes you didn’t mean to expose.
- Renaming or removing an output is a breaking change. It gets a major version, the same as removing a variable.
That last point catches people out. Adding outputs is safe. Taking them away breaks every caller that referenced them, whether you knew they existed or not.
Providers flow down, not in
Child modules shouldn’t contain provider blocks. They declare what they need in required_providers, and the caller supplies the configuration.
This isn’t just tidiness. A module that contains its own provider configuration can’t be used with count, for_each or depends_on. So the conditional database from last week’s golden path simply wouldn’t work if the database module had its own provider "azurerm" block inside it.
Where this really matters in Azure is anything that has to reach outside the workload’s subscription, typically into the connectivity or hub subscription. The helper declares that it expects a second provider:
terraform {
  required_providers {
    azurerm = {
      source                = "hashicorp/azurerm"
      configuration_aliases = [azurerm.connectivity]
    }
  }
}
The caller passes it in explicitly:
module "dns_record" {
  source = "git::https://github.com/<org>/tf-helper-dns-record.git?ref=v1.1.0"

  providers = {
    azurerm              = azurerm
    azurerm.connectivity = azurerm.connectivity
  }
}
Now it’s visible in the calling code exactly which module can touch the hub, and which identity it’s doing it as. That’s a security boundary written in the open rather than hidden inside a module.
Wiring optional modules together
Last week’s golden path called the database module with count. That has a knock-on effect for anything that references it, because module.database is now a list, not a single object.
module.database[0].id works, until the database is disabled and the plan fails with an index error. The cleaner convention is one():
output "database_id" {
  value = one(module.database[*].id)
}
If the database exists, you get its ID. If it doesn’t, you get null. Anything downstream can handle that, instead of every caller writing its own conditional around an index that might not be there.
Pulling it together
From the consumer’s side, the result should look almost boring:
module "orders_api" {
  source = "git::https://github.com/<org>/tf-golden-path-web-app.git?ref=v2.3.0"

  name        = "orders-api"
  environment = "prod"

  database = {
    enabled = true
  }
}
One pinned source. Typed, validated inputs. No helpers called directly, no provider blocks hidden anywhere, and nothing that depends on which branch someone last pushed to.
That’s the point of calling conventions. The boundaries decide what each module is responsible for. The conventions decide whether you can change any of them without breaking everyone who depends on them.
Next week I’ll cover testing: why it’s the part that actually enforces all of this, and why it’s governance rather than a nice-to-have.